Institutional Knowledge Injection for Self-Hosted Agents
Bounded, trigger-based procedures beat prompt-stuffing for self-hosted agents.
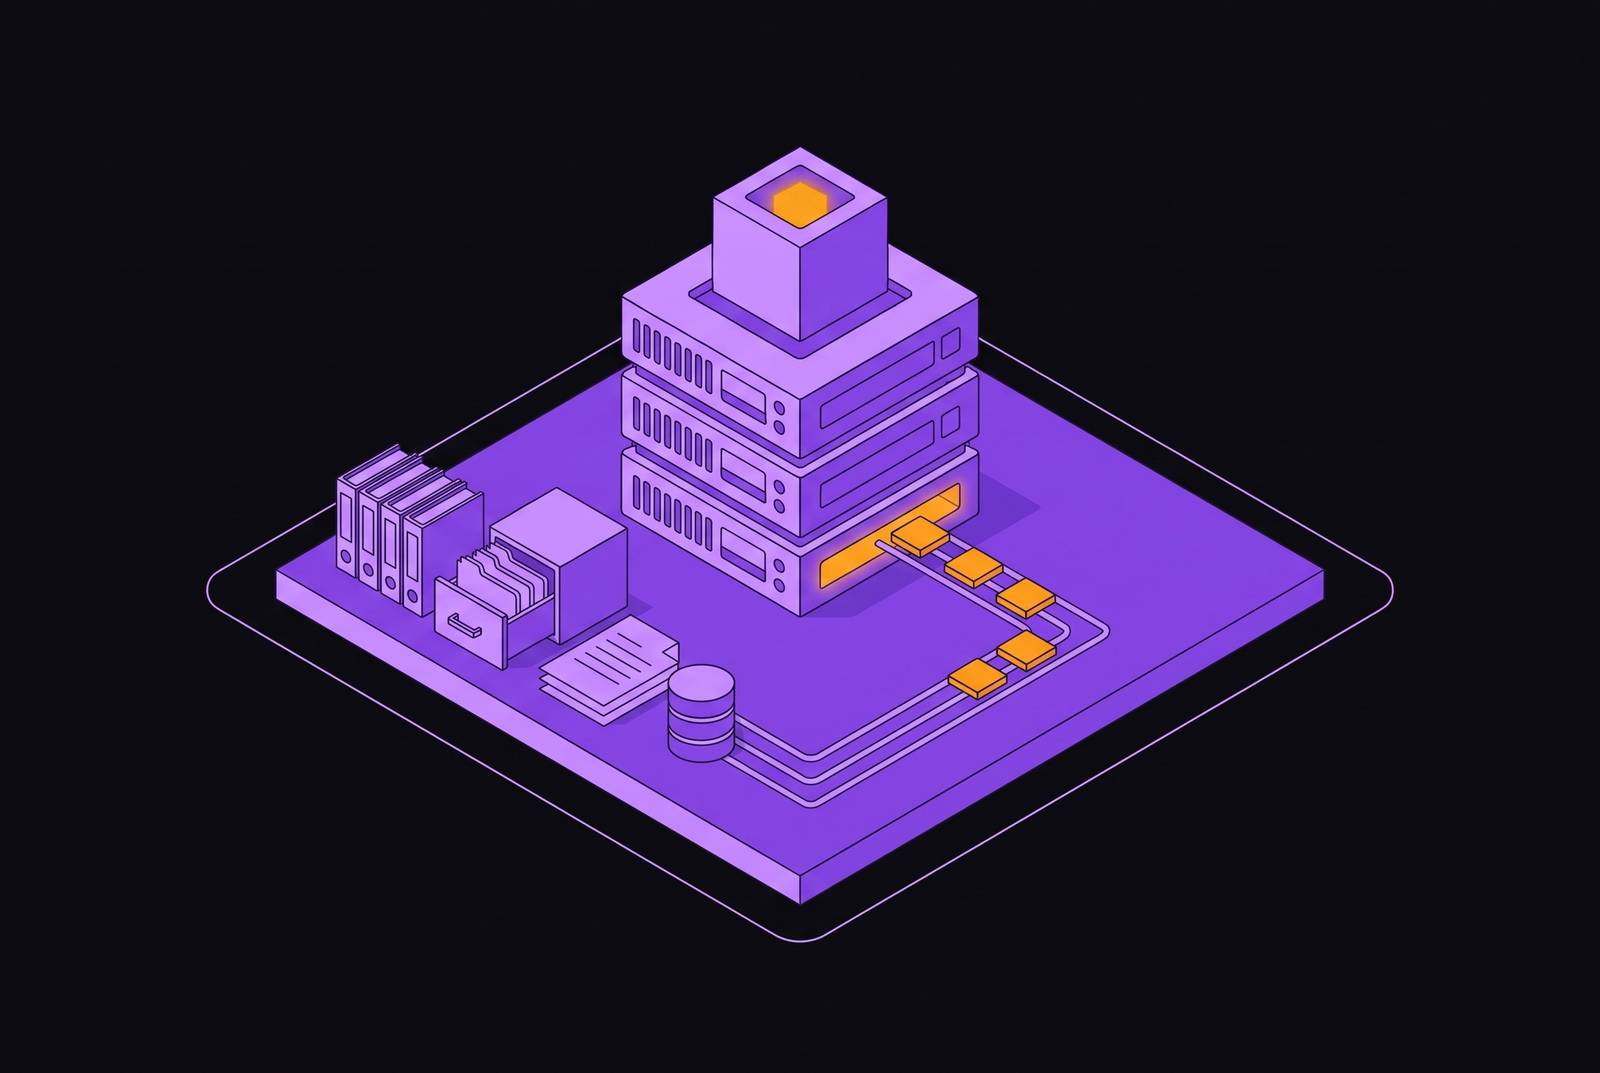
Institutional knowledge injection for self-hosted agents is an architecture problem. Agents need bounded procedures loaded when a task calls for them. For multi-step work, persistent AI agent infrastructure must keep task state and loaded context between tool calls, which a stateless serverless function cannot do on its own.
Why institutional knowledge fails agents before retrieval even begins
An agent has access to the full policy wiki but still asks a question a human employee would not ask. Or it finds the right policy and takes the wrong workflow branch. Wiki pages, Confluence docs, Slack threads, and policy PDFs assume a reader who already knows which rules apply, how exceptions work, and when to stop. Agents need those connections stated.
Putting those documents into the system prompt gives the agent more text while burying the relevant instructions among unrelated policies. Undifferentiated retrieval-augmented generation, or RAG, has a different delivery method but the same weakness. It can return the right facts without the decision rule that turns them into action. Both approaches treat documents as the unit of knowledge when the agent needs a procedure it can follow.
What makes a unit of knowledge agent-loadable
A usable knowledge unit answers three questions explicitly. It says when it applies, what to do, and where its authority ends. Its trigger condition ties it to a task or agent state. Its procedure has steps, decision branches, and exit conditions. Its scope boundary tells the agent when to load another unit instead of extending instructions beyond their intended use.
These requirements follow from the failure of document-shaped knowledge. The Agent Skills architecture illustrates one way to package them through a structured SKILL.md instruction file with optional scripts, reference documents, and assets. The filename is not what makes the package useful. The useful part is that the agent can discover a bounded procedure and load it as a complete unit. The agent can still use supporting documents without keeping them in the prompt.
This also separates skills from tools. A tool executes an operation and returns a result, while a skill supplies the procedure that guides the agent’s use of its capabilities. That distinction allows progressive disclosure. A unit can point to a sub-skill that becomes relevant only after a particular branch is taken. The agent then gains the context for that branch without loading every possible path in advance.
The token economics of injection-on-demand versus always-loaded context
An always-loaded library makes context cost grow with organizational knowledge. A library of dozens of workflows can consume a substantial fraction of a context window before a user prompt arrives. Most requests do not need that whole library. Selective injection ties the active context to the procedures the task at hand needs, so a growing library adds less cost to requests that do not need the new procedures.
The Agent Skills architecture characterizes selective injection as roughly a 50× reduction in startup token cost. That characterization applies only to startup cost. A narrow workflow no longer shares the model’s attention with every other workflow the organization has documented.
Prefix caching adds another reason to keep context disciplined. Modern inference infrastructure can cache key-value activations for an unchanged prefix, including the system prompt, tool schema, and standing policies. Keeping that prefix small and stable supports cache reuse and reduces time-to-first-token. Procedures that vary with the task belong in the part of the context that is loaded on demand. Packing the entire knowledge library into the standing prefix confuses permanent instructions with task-specific guidance.
Codifying org knowledge into discrete, injectable units: the authoring process
To build these units, start by separating policies, procedures, and decision rules in the existing documentation. Policies constrain what the agent may do, procedures define a sequence, and decision rules select a branch. A guide written in prose about loan application status may mix all three. Decompose that guide before trying to turn it into an injectable procedure.
Write the trigger before writing the steps. “When the user asks about X” leaves more room for interpretation than a predicate tied to an operation and a known state. A unit can apply when a task involves modifying a customer record in the billing system and the account is flagged as disputed.
Write the unit itself as numbered steps with testable outcomes. Each step should make the conditions for proceeding clear to the agent, and each branch should state what happens if its condition is met or not met. For a loan application status check, the boundary between reporting status and modifying the application must be explicit. The unit should name the separate procedure for work outside its scope.
Add references to policy documents, approval matrices, and field definitions. Load them only when the relevant branch needs them. Also assign an owner, a version, and a reason for review during authoring, rather than treating governance as deployment cleanup. A superseded policy is not a harmless omission. Once packaged as a procedure, it becomes an instruction to do the wrong thing.
How injection works in persistent AI agent infrastructure vs serverless functions
The runtime connects those authored triggers to live task state. It maintains a registry of available units and evaluates which triggers match at each planning step. A match leads to loading a complete procedure. Unlike a retrieved text chunk, that procedure becomes part of the agent’s execution context, directing how it handles the next part of the task.
Filesystem packaging makes the unit addressable and versioned. The runtime can identify the particular artifact loaded for a task in its audit record. It also tracks active units and unloads them when the task leaves their scope. Without that removal, selective injection gradually becomes another full-context prompt. Context management belongs in the runtime.
A stateless request/response handler on its own cannot know which procedure is still in scope partway through a workflow. A container that dies between requests likewise cannot be the only place that holds that working state. Persistent runtimes and serverless functions therefore need to be compared on state retention. Injection-on-demand needs a persistent runtime layer that maintains task position, loaded units, and their scope across the workflow.
Why the knowledge injection surface is also an attack surface
A loader that changes an agent’s procedure is a powerful control point. If it accepts the wrong unit or a tampered unit, the failure is procedural misdirection. Parallax argues that prompt-level guardrails are insufficient because safety instructions and adversarial inputs pass through the same attention mechanism.
Bad Memory, from the University of Washington, studied file-based memory in systems including Claude Code and OpenAI Codex. It found that payloads already planted in persistent memory files could attack sessions now and in the future, though the results differed a great deal across models and systems. The connection to injectable units is direct but limited. Both use files that can influence later behavior, so trust in the loading path cannot rest on the fact that a file is local or persistent.
Agent Data Injection Attacks are Realistic Threats to AI Agents, from researchers including Seoul National University and UIUC, shows another way through that boundary. Malicious data can masquerade as trusted data without presenting itself as an instruction. The research found up to 50.0% attack success against state-of-the-art agent defenses. For knowledge loading, this means that separating instructions from data is not enough if referenced data is itself treated as trustworthy without validation. Parallax also describes propagation across agent layers, making inherited context another route for poisoned material.
Treat units as code. Version and sign them, load them from an integrity-verified source, and keep referenced assets on a read-only, audited path separate from agent-writable files. Apply Parallax’s Cognitive-Executive Separation principle by separating selection and loading from execution, with validation between them. Where a procedure modifies records, configurations, or external systems, capturing pre-action state supports rollback. These controls protect the path from discovery to action.
Persistent agent state and what it means for knowledge unit lifecycle
Persistent context makes a loaded unit more than a one-request concern. An agent may retain its instructions after the session that introduced them, which extends both the security risk and the risk of stale policy. Updating the source file is not enough. If an active agent still holds the old procedure, that procedure can continue directing its behavior until the runtime invalidates it.
Lifecycle controls therefore have to operate on loaded state. A validity period or version tag belongs in metadata that the runtime enforces. Policy updates should invalidate cached loads of the prior version across active sessions as well as new ones. Agents that update their own knowledge files need a gated write path. Otherwise, material made while the agent runs can come back later and seem to carry authority.
A known-good snapshot taken before a knowledge update allows the new unit to be tested against that state before wider deployment. The capability serves a specific lifecycle purpose. It gives the team a controlled point from which to assess a changed procedure, rather than discovering its effects only after every active agent has adopted it.
Applying injection architecture in regulated environments where policy is not optional
Consider an agent taking the wrong branch during insurance claim triage because a compliance rule was not embedded in the procedure. The policy may have been available through search. Availability does not establish when the rule must apply. A retrieved HIPAA policy document can tell the agent that a restriction exists without tying it to the step where the agent accesses protected health information.
An injectable procedure puts the rule at that decision point. The step that accesses PHI includes the minimum-necessary-access constraint as a branch. Access to the unit also needs governance. A PHI-adjacent procedure can be limited to agents operating under a valid BAA configuration, connecting permission to load the procedure with permission to handle the data. Packaging alone does not replace those controls.
The execution record must also explain the procedure followed. Recording actions without identifying the loaded unit leaves a gap in reconstructing why the agent took a particular path. Versioned units provide that missing reference in the audit trail. The same procedural discipline applies to legacy EHR systems, loan origination systems, and document management systems without modern APIs. Their GUI navigation paths need encoded instructions rather than in-context improvisation, with the applicable policy constraints attached to the relevant steps.
Structuring the injection pipeline: from knowledge authoring to agent-ready deployment
Deployment starts with codification, because packaging cannot add decision logic that is missing. Raw policies, procedures, and decision rules are turned into units with clear bounds, triggers, and exit conditions. Packaging then makes each unit independently loadable, with references to supporting assets. The handoff turns a document bundle into a procedure. Skipping that distinction recreates the original retrieval failure inside a new file format.
Units go into a versioned, signed registry that the runtime can read but cannot freely rewrite, and privileged changes have their own audit trail. The runtime selects matching units, tracks their active scope, and removes them when that scope ends.
When the runtime enforces validity metadata and invalidates prior loads, active sessions are kept from silently following procedures that are no longer in use. Gated approval prevents self-modifying agents from bypassing the same publication controls. Without those stages, a correct unit at deployment can become a source of compliance drift later. Predictable behavior depends on the whole path.
That path has a persistent infrastructure dependency. A runtime must keep execution context through a multi-step workflow so it can track unit scope, enforce scope exit, and record loads as events that can be audited. A stateless function alone supplies no such continuity.